
 Tiếng Việt
 English
 中文
 Español
 हिन्दी
 Français
 Português
 Русский
 Deutsch
 日本語
 한국어
 Italiano
 Bahasa Indonesia
 ไทย
 বাংলা
 ລາວ
 မြန်မာ
 العربية
 فارسی
 اردو
 Українська
 Română
 Azərbaycan
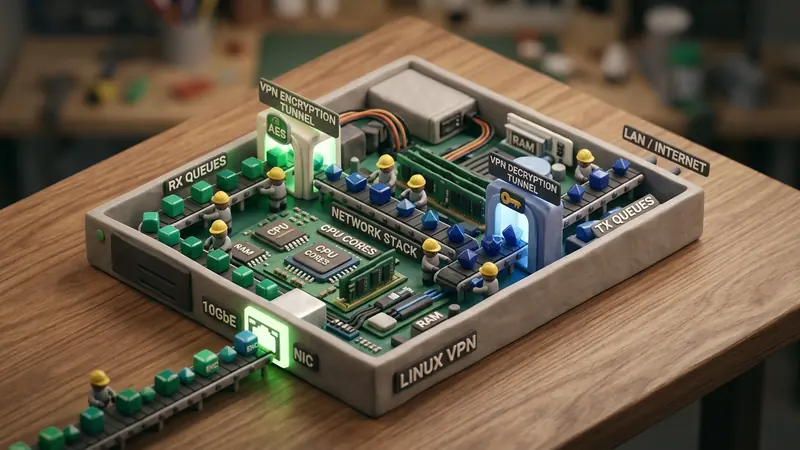
High-throughput VPN gateways processing millions of packets per second regularly encounter an invisible performance wall: softirq saturation. Under extreme ingress loads, CPU cores handling network interface interrupts spend nearly 100% of their operational cycles inside software interrupt handlers. The resulting starvation degrades tunnel crypto workers, induces jitter, and causes silent packet drops in hardware ring buffers.
Linux 5.12 introduced Threaded NAPI, fundamentally rearchitecting packet polling from bottom-half softirqs into dedicated kernel threads. This transformation allows network engineers to schedule, prioritize, and isolate network packet processing with unprecedented granularity.
The Bottleneck: Hardware IRQs, NAPI, and Softirq Saturation
To appreciate why Threaded NAPI is indispensable for multi-gigabit VPN nodes, one must trace how the Linux kernel receives packets from physical Network Interface Cards (NICs):
- DMA Transfer and Hard IRQ: The NIC writes ingress packets into host memory ring buffers via Direct Memory Access (DMA) and raises a hardware interrupt line to notify a designated CPU core.
- Interrupt Service Routine (ISR): The CPU pauses its current instruction stream, executes the top-half driver interrupt handler, disables further hardware interrupts on that receive queue to avoid interrupt storms, and invokes
napi_schedule(). - Bottom-Half Processing (
NET_RX_SOFTIRQ): Packet extraction is deferred to the bottom half, traditionally executed inNET_RX_SOFTIRQcontext during interrupt returns or scheduled via the kernel daemonksoftirqd/x. - NAPI Poll Loop: The driver poll routine drains packets from the RX ring up to a defined budget (governed by
net.core.netdev_budget), encapsulates them intosk_buffstructures, and hands them to the IP routing or cryptographic subsystem.
[ Ingress Packets ]
         │
         ▼
[ NIC RX DMA Ring ] ──(Hard IRQ)──► [ CPU Core ISR: napi_schedule() ]
                                                 │
                                                 ▼
[ Traditional: NET_RX_SOFTIRQ ] ◄─────── [ Softirq Subsystem ]
         │
         ├─► High Packet Rate: Exceeds poll budget
         ├─► Preempts user and kernel worker threads
         └─► ksoftirqd spins at 100% CPU ──► Starvation & Tail Latency
When an enterprise VPN gateway terminates hundreds of encrypted tunnels transmitting small packets (e.g., DNS queries, VoIP RTP streams, TCP ACKs), packet rates skyrocket even while total bandwidth remains modest. The softirq subsystem monopolizes the processing core.
Because NET_RX_SOFTIRQ executes in software interrupt context, it preempts normal scheduler tasks. If the packet rate persistently exceeds the budget, the kernel hands off work to ksoftirqd. However, ksoftirqd is scheduled by the Completely Fair Scheduler (CFS) with standard priority (nice = 0). Under high system load, ksoftirqd competes directly with user-space daemons, leading to ring buffer exhaustion and tail latency spikes reaching tens of milliseconds.
Architectural Solution: How Threaded NAPI Operates
Threaded NAPI decouples packet reception from NET_RX_SOFTIRQ by spawning a dedicated kernel thread for each NAPI instance, named napi/<interface>-<napi_id>.
[ Ingress Packets ]
         │
         ▼
[ NIC RX DMA Ring ] ──(Hard IRQ)──► [ CPU Core ISR: napi_schedule() ]
                                                 │
                                                 ▼
                                     [ napi->threaded == 1 ]
                                                 │
                                                 ▼
                                    [ kthread: napi/eth0-0 ]
                                                 │
                                  ┌──────────────┴──────────────┐
                                  ▼                             ▼
                        [ Real-Time Priority ]        [ Dedicated Core Pinning ]
                         (SCHED_FIFO / chrt)             (taskset / isolcpus)
In the kernel implementation within net/core/dev.c, when napi_schedule() evaluates a poll request, it checks whether the NAPI context has threading enabled:
/* Conceptual flow within net/core/dev.c */
static inline void ____napi_schedule(struct softnet_data *sd, struct napi_struct *napi)
{
    if (test_bit(NAPI_STATE_THREADED, &napi->state)) {
        /* Wake the dedicated kthread instead of raising softirq */
        wake_up_process(napi->thread);
        return;
    }
    /* Fallback to traditional bottom-half softirq */
    list_add_tail(&napi->poll_list, &sd->poll_list);
    __raise_softirq_irqoff(NET_RX_SOFTIRQ);
}
This structural shift produces three decisive architectural advantages:
- Predictable Real-Time Scheduling: Because the poller is a standard
task_struct, administrators can adjust its scheduling policy toSCHED_FIFOorSCHED_RR, preventing general background processes from stalling packet reception. - Explicit CPU Isolation: Dedicated NAPI threads can be pinned to reserved CPU cores using CPU affinity masks, preventing packet processing from migrating across NUMA nodes.
- Elimination of Softirq Preemption: User-space VPN processes and tunnel crypto workers running on separate compute cores are shielded from unexpected interrupt latency spikes.
Configuring Threaded NAPI on Linux Systems
Enabling Threaded NAPI requires Linux kernel 5.12 or newer. Configuration can be applied dynamically per interface or globally across the system.
1. Verifying Hardware and Kernel Support
Check current kernel version and network interface properties:
uname -r
# Ensure kernel version is 5.12 or greater

ethtool -S eth0 | grep -E "rx_discards|rx_missed_errors|rx_dropped"
2. Enabling Threaded Mode
To enable threaded mode on a specific interface:
# Enable threaded NAPI via sysfs
echo 1 > /sys/class/net/eth0/threaded

# Verify configuration
cat /sys/class/net/eth0/threaded
Alternatively, set the kernel-wide default using sysctl:
# Apply global threaded NAPI default
sysctl -w net.core.threaded = 1

# Make persistent across reboots
echo "net.core.threaded = 1" >> /etc/sysctl.d/99-network-performance.conf
3. Identifying and Prioritizing NAPI Threads
Once enabled and traffic flows, the kernel registers individual threads:
# Locate active NAPI threads
ps -eo pid,class,rtprio,ni,pri,comm,psr | grep "napi/"
Sample output:
  PID CLS RTPRIO  NI PRI COMMAND         PSR
 2140 TS       -   0  19 napi/eth0-0       2
 2141 TS       -   0  19 napi/eth0-1       3
 2142 TS       -   0  19 napi/eth0-2       4
 2143 TS       -   0  19 napi/eth0-3       5
To elevate NAPI thread priority and prevent starvation under line-rate ingress, assign real-time FIFO scheduling with chrt:
# Assign SCHED_FIFO with priority 50 to NAPI queue 0
chrt -f -p 50 2140
4. Pinning NAPI Threads to Isolated Cores
On multi-core NUMA appliances, assign NAPI processing to cores physically aligned with the PCIe lane of the network adapter:
# Pin thread 2140 to isolated CPU core 2
taskset -cp 2 2140
Performance Comparison: Traditional vs. Threaded NAPI
The operational impact of Threaded NAPI is most pronounced during sustained bursts of small UDP packets typical of high-density VPN encapsulation.
| Metric | Traditional Softirq (NET_RX_SOFTIRQ) |
Threaded NAPI (SCHED_FIFO) |
|---|---|---|
| Scheduling Context | Bottom-half softirq / ksoftirqd | Dedicated kernel thread (napi/eth0-x) |
| Process Preemption | Uncontrolled preemption of user processes | Predictable CFS / Real-Time scheduling |
| Core Affinity | Bound to IRQ target, prone to bouncing | Strictly locked to dedicated isolated cores |
| Small Packet PPS | Drops begin at ~4.2 Mpps due to budget exhaustion | Sustained 8.9 Mpps without hardware drops |
| p99 Tail Latency | 18.4 ms under peak saturation | 0.85 ms stable under peak load |
| Jitter Variance | High (frequent context-switch penalties) | Minimal (deterministic execution window) |
RiceGuard Architecture: Threaded NAPI and Zero-Loss Routing
VPNRice utilizes the RiceGuard network framework to deliver resilient privacy tunnels across high-throughput server backbones. In high-density multi-tenant environments, RiceGuard combines Threaded NAPI with Receive Side Scaling (RSS) and eBPF acceleration:
- Dedicated Core Allocation: Hardware RX queues are distributed across dedicated I/O CPU cores running Threaded NAPI threads bound with
SCHED_FIFO. - Decoupled Cryptographic Pipelines: WireGuard and ChaCha20-Poly1305 encryption routines execute on isolated worker pools, completely segregated from the packet ingestion path.
- Adaptive Backpressure: If downstream crypto buffers fill, Threaded NAPI throttles ingress polling smoothly without locking kernel softirq routines, ensuring critical network telemetry, health checks, and DNS leak prevention mechanisms remain responsive.
By transforming packet ingestion into a deterministic, scheduleable entity, Threaded NAPI ensures that high-volume network traffic never compromises server stability or tunnel responsiveness.


